

Clustering
High-availability topologies aligned to the platform.
- Oracle RAC
- Solaris Cluster
- Linux Cluster
- Oracle Linux Cluster
We design clustering, redundancy and failover to reduce interruptions and control platform behavior during failures.
Discuss Your Project →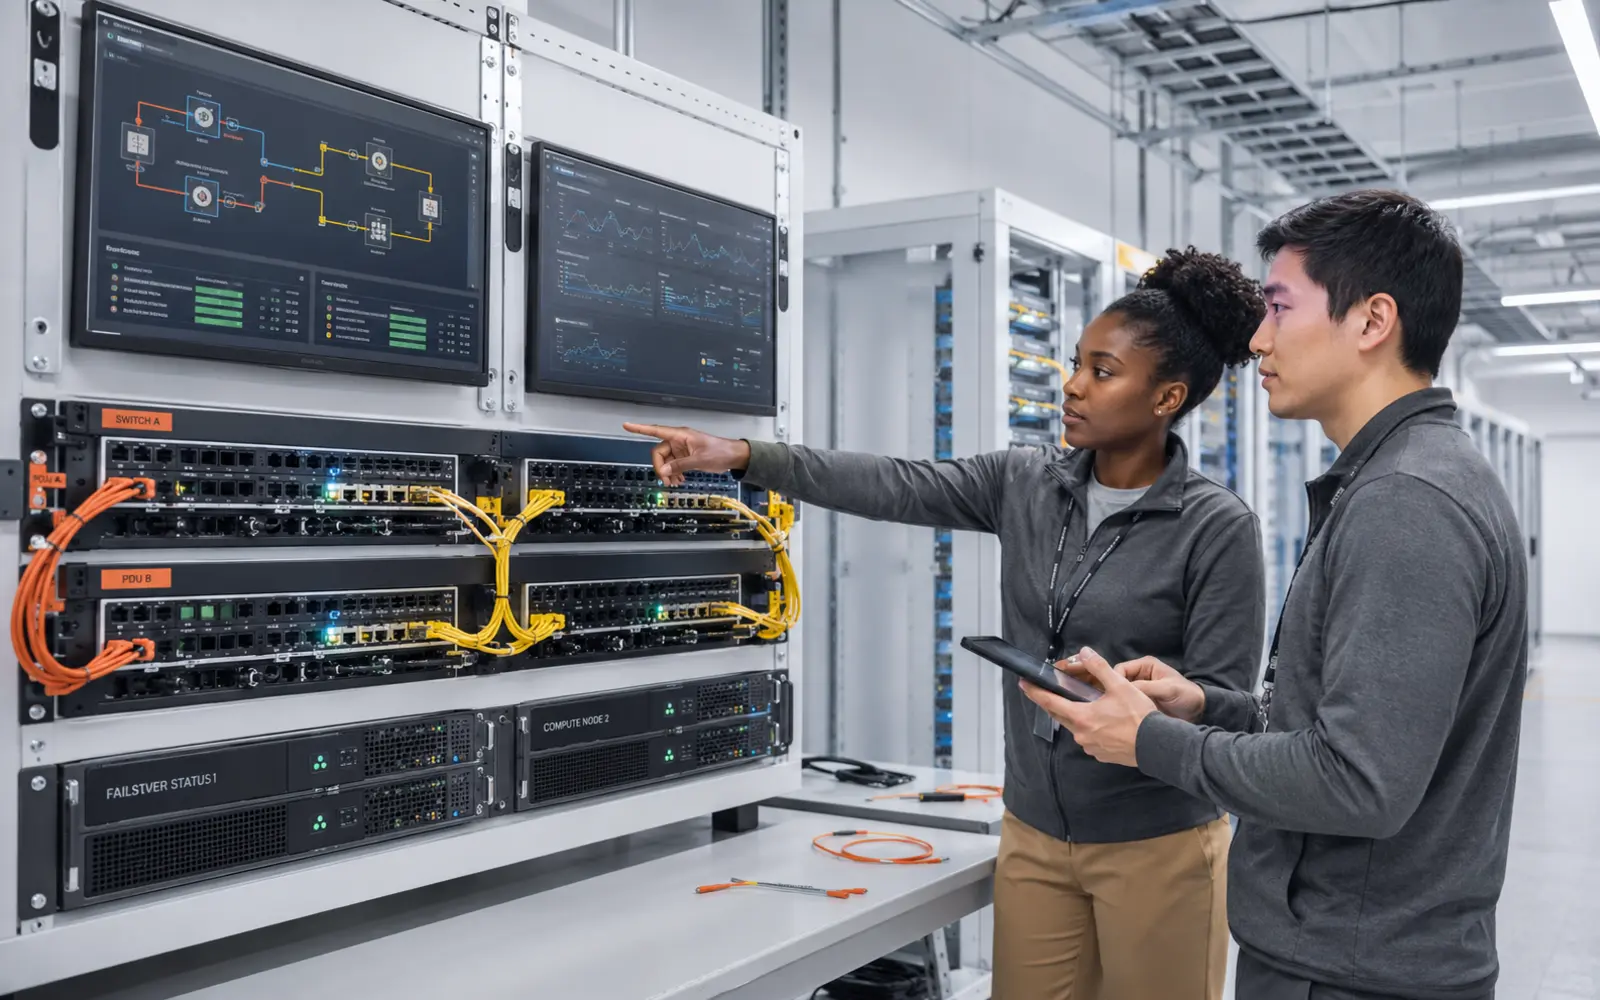
Redundancy and clustering are designed around service, operating system, database, network and storage.
High-availability topologies aligned to the platform.
High availability for IBM Power and AIX.
A configured cluster is not enough: behavior is validated during component loss and maintenance.
Controlled execution of failure scenarios.
Documentation makes behavior known and repeatable.
Duplicating components is not enough. We review what the cluster protects, what remains a single point and how the service behaves during maintenance or failure.
We define which process or resource must remain available.
The cluster must detect, isolate and recover correctly.
Shared paths must also be redundant and tested.
The design must include maintenance, testing and procedures.
Architecture follows real dependencies and service criticality.